langlocalizer 🟡 Beta
Subjects |
4 — |
Maturity |
🟡 Beta — Complete (all planned participants released, fMRIPrep derivatives, README) but neither validated nor substantially reused yet. |
Data |
🧠 fMRI — 1.1 h/subject |
📊 Controlled — 1.1 h/subject |
|
📐 Contrasts — 4 contrasts |
|
Assets |
📁 BIDS · 🧠 fMRIPrep · timeseries |
How to cite
Bilgin, I., Borghesani, V., DuPre, E., St-Laurent, M., Pinsard, B., et al. (2027). Deep phenotyping the language network: assessing inter- and intra-subject variability across a wide range of conditions.
Contributors
Conceptualization: Isil P. Bilgin · Valentina Borghesani · Simona M. Brambati · Lune Bellec
Data curation: Isil P. Bilgin · Elizabeth DuPre · Marie St-Laurent · Basile Pinsard
Formal analysis: Isil P. Bilgin
Funding acquisition: Lune Bellec
Investigation: Isil P. Bilgin · Marie St-Laurent
Methodology: Isil P. Bilgin · Valentina Borghesani
Project administration: Marie St-Laurent · Basile Pinsard · Julie A. Boyle · Lune Bellec
Resources: Julie A. Boyle · Lune Bellec
Software: Isil P. Bilgin · Elizabeth DuPre · Marie St-Laurent · Basile Pinsard
Supervision: Valentina Borghesani · Simona M. Brambati · Lune Bellec
Visualization: Isil P. Bilgin
Writing – original draft: Isil P. Bilgin
Writing – review & editing: Valentina Borghesani · Simona M. Brambati · Elizabeth DuPre · Lune Bellec
Funding: Courtois Foundation · Institut de valorisation des données (IVADO)
Overview
Four participants (sub-01, sub-02, sub-03, sub-05) completed three sessions, one week apart, of standard language localizers while fMRI was acquired. All four are right-handed and fluent in both English and French; two are native English speakers and two native French speakers. Each session comprises two runs of each of four tasks (about 38 min of acquisition), interleaved in randomized order with non-language CNeuroMod tasks.
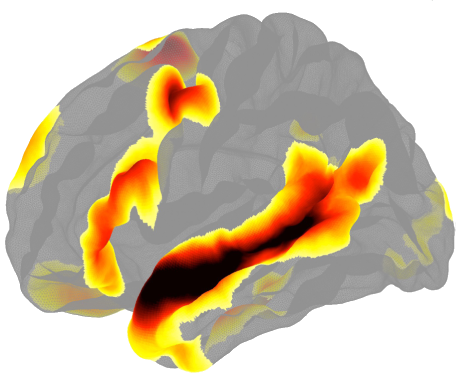
What makes the dataset distinctive is that it systematically crosses modality (reading vs. listening) and language (English vs. French) within the same individuals, with three repetitions of the whole protocol. This deep-sampling design makes it possible to separate variability in the topography of the language network between participants from variability within a participant across sessions, modalities and languages. It complements the CNeuroMod HCP-TRT and movie-watching data, and was used in the manuscript Deep phenotyping the language network: assessing inter- and intra-subject variability across a wide range of conditions (Bilgin et al., 2027, in preparation) to define subject-specific language regions of interest. Those ROIs are not part of this dataset: they will be distributed with the atlases in anat/atlases.
Tasks
All localizers follow block designs contrasting intact language with a control, from the Fedorenko lab’s functional localizers:
reading (
task-reading, VisualLoc): English sentences vs. non-word sequences (Fedorenko et al., 2010). 5 min 58 s per run, 16 experimental blocks of 18 s (8 per condition) and 5 fixation blocks of 14 s.listening (
task-listening, AudioLoc): English auditory passages vs. acoustically degraded versions of the same passages (Scott et al., 2016). Same block structure as the reading task.aliceEn and aliceFr (AliceLoc, Ayyash et al., 2021): passages from Alice in Wonderland in English or French, acoustically degraded versions of the passages, and passages in an unfamiliar language (Tamil). 4 min 12 s per run, 12 experimental blocks of 18 s (4 per condition) and 4 fixation blocks of 12 s. In the manuscript the two versions are recoded as first (L1) and second (L2) language of each participant.
Tasks were presented with custom PsychoPy scripts synchronized to the scanner trigger. Sounds were delivered through Sensimetrics S15 insert headphones.
Acquisition
Data were acquired on a Siemens Prisma Fit 3T scanner with a 64-channel head/neck coil at the Unité de Neuroimagerie Fonctionnelle (UNF), CRIUGM, Montréal, following the CNeuroMod protocol (TR = 1.49 s, 2 mm isotropic voxels, multiband acceleration factor 4).
Preprocessing
fmriprep: fMRIPrep preprocessing.mriqc: image quality metrics.tsnr: temporal SNR maps.timeseries: parcellated timeseries.